LT-DETR
Lightly's LTDETRv2: a real-time DETR on EdgeCrafter ECViT backbones, three sizes on COCO's 80 classes, AGPL-3.0 or a paid Lightly license.
Conditional for size s: code AGPL-3.0-only, weights AGPL-3.0-only. Measured on our RTX 4090: 30.4 ms median, 632 MiB VRAM peak. We scored it 51.0 box AP on COCO val2017. PyTorch weights, 40 MB.
Conditional for size m: code AGPL-3.0-only, weights AGPL-3.0-only. Measured on our RTX 4090: 31.6 ms median, 704 MiB VRAM peak. We scored it 53.5 box AP on COCO val2017. PyTorch weights, 81 MB.
Conditional for size l: code AGPL-3.0-only, weights AGPL-3.0-only. Measured on our RTX 4090: 32.2 ms median, 768 MiB VRAM peak. We scored it 56.4 box AP on COCO val2017. PyTorch weights, 129 MB.
License
Conditional
Conditional
Conditional
- Code
- AGPL-3.0-onlychecked 10 Nov 2026
- Weights
- AGPL-3.0-onlyall sizes, checked 10 Nov 2026
AGPL-3.0 for code and weights: Lightly's licensing page says AGPL-3.0 covers weights trained with LightlyTrain, and the notice stored in the checkpoint says commercial training and inference need Lightly's paid Commercial License. The ECViT backbone came from EdgeCrafter's Apache-2.0 release of 2026-03, before EdgeCrafter's non-commercial relicense on 2026-08-24. That backbone is distilled from a DINOv3 teacher and its code is modified from DINOv3; whether DINOv3's terms reach the weights isn't settled.
AGPL-3.0 for code and weights: Lightly's licensing page says AGPL-3.0 covers weights trained with LightlyTrain, and the notice stored in the checkpoint says commercial training and inference need Lightly's paid Commercial License. The ECViT backbone came from EdgeCrafter's Apache-2.0 release of 2026-03, before EdgeCrafter's non-commercial relicense on 2026-08-24. That backbone is distilled from a DINOv3 teacher and its code is modified from DINOv3; whether DINOv3's terms reach the weights isn't settled.
AGPL-3.0 for code and weights: Lightly's licensing page says AGPL-3.0 covers weights trained with LightlyTrain, and the notice stored in the checkpoint says commercial training and inference need Lightly's paid Commercial License. The ECViT backbone came from EdgeCrafter's Apache-2.0 release of 2026-03, before EdgeCrafter's non-commercial relicense on 2026-08-24. That backbone is distilled from a DINOv3 teacher and its code is modified from DINOv3; whether DINOv3's terms reach the weights isn't settled.
On our RTX 4090, measured
30.4ms median
p90 31.0 ms, fp16, batch 1, 640x640
- VRAM peak
- 632 MiB
- Status
- Runs as is
Environment, 10 Nov 2026
NVIDIA GeForce RTX 4090, driver 580.173.02, CUDA 13.0, torch 2.14.1+cu130, Python 3.12.9, lightly-train==0.18.0. Baseline 789 MiB. 10 warm-up + 100 timed. Scope: predict(): pre-processing, forward pass and post-processing; input file decoded beforehand.
Reported5.4 msNVIDIA T4, TensorRT 10.13.3.9, FP16, batch size 1, 640x640 input; average latency. The docs don't say whether pre- or post-processing is inside the time.Source: LightlyTrain docs, Object Detection, Benchmark Results, COCO table (Latency (ms)) and the text above it (TensorRT 10.13.3.9, T4, batch size 1); FP16 from the page's opening paragraph. https://github.com/lightly-ai/lightly-train/blob/0d0ec65bea3ef952ae51f93440d9986333dc5b79/docs/source/object_detection.md
Accuracy
51.0box APmeasured
COCO val2017, box AP, 5,000 images, fp16, pycocotools==2.0.11 · 10 Nov 2026
Paper 50.7 COCO mAP50-95LightlyTrain docs, Object Detection, Benchmark Results table (Val mAP50:95, 640x640), https://github.com/lightly-ai/lightly-train/blob/0d0ec65bea3ef952ae51f93440d9986333dc5b79/docs/source/object_detection.md
31.6ms median
p90 31.9 ms, fp16, batch 1, 640x640
- VRAM peak
- 704 MiB
- Status
- Runs as is
Environment, 10 Nov 2026
NVIDIA GeForce RTX 4090, driver 580.173.02, CUDA 13.0, torch 2.14.1+cu130, Python 3.12.9, lightly-train==0.18.0. Baseline 790 MiB. 10 warm-up + 100 timed. Scope: predict(): pre-processing, forward pass and post-processing; input file decoded beforehand.
Reported7.95 msNVIDIA T4, TensorRT 10.13.3.9, FP16, batch size 1, 640x640 input; average latency. The docs don't say whether pre- or post-processing is inside the time.Source: LightlyTrain docs, Object Detection, Benchmark Results, COCO table (Latency (ms)) and the text above it (TensorRT 10.13.3.9, T4, batch size 1); FP16 from the page's opening paragraph. https://github.com/lightly-ai/lightly-train/blob/0d0ec65bea3ef952ae51f93440d9986333dc5b79/docs/source/object_detection.md
Accuracy
53.5box APmeasured
COCO val2017, box AP, 5,000 images, fp16, pycocotools==2.0.11 · 10 Nov 2026
Paper 53.1 COCO mAP50-95LightlyTrain docs, Object Detection, Benchmark Results table (Val mAP50:95, 640x640), https://github.com/lightly-ai/lightly-train/blob/0d0ec65bea3ef952ae51f93440d9986333dc5b79/docs/source/object_detection.md
32.2ms median
p90 35.8 ms, fp16, batch 1, 640x640
- VRAM peak
- 768 MiB
- Status
- Runs as is
Environment, 10 Nov 2026
NVIDIA GeForce RTX 4090, driver 580.173.02, CUDA 13.0, torch 2.14.1+cu130, Python 3.12.9, lightly-train==0.18.0. Baseline 790 MiB. 10 warm-up + 100 timed. Scope: predict(): pre-processing, forward pass and post-processing; input file decoded beforehand.
Reported10.78 msNVIDIA T4, TensorRT 10.13.3.9, FP16, batch size 1, 640x640 input; average latency. The docs don't say whether pre- or post-processing is inside the time.Source: LightlyTrain docs, Object Detection, Benchmark Results, COCO table (Latency (ms)) and the text above it (TensorRT 10.13.3.9, T4, batch size 1); FP16 from the page's opening paragraph. https://github.com/lightly-ai/lightly-train/blob/0d0ec65bea3ef952ae51f93440d9986333dc5b79/docs/source/object_detection.md
Accuracy
56.4box APmeasured
COCO val2017, box AP, 5,000 images, fp16, pycocotools==2.0.11 · 10 Nov 2026
Paper 56 COCO mAP50-95LightlyTrain docs, Object Detection, Benchmark Results table (Val mAP50:95, 640x640), https://github.com/lightly-ai/lightly-train/blob/0d0ec65bea3ef952ae51f93440d9986333dc5b79/docs/source/object_detection.md
Weights
PyTorch
- Size
- 40 MB
- sha256
f8aefe499be1579c55bfcb288f623399ea5f4efef0c5a5f00960663efeda4f49
PyTorch
- Size
- 81 MB
- sha256
723357e921c77f8041f44875f5edce8645412ccc5d13fb7dca93271d525c1641
PyTorch
- Size
- 129 MB
- sha256
62ff87cd792c87e00f53da0c62ae91a63927e0ce2088c5cf018edffa513ccb6c
Outputs on the shared test photos
Same photos and one score threshold for every model of this task. Failures are marked.
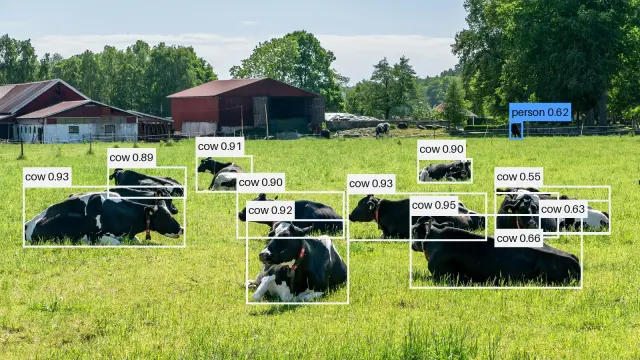 cows-pastureFails: labels a distant cow as a person
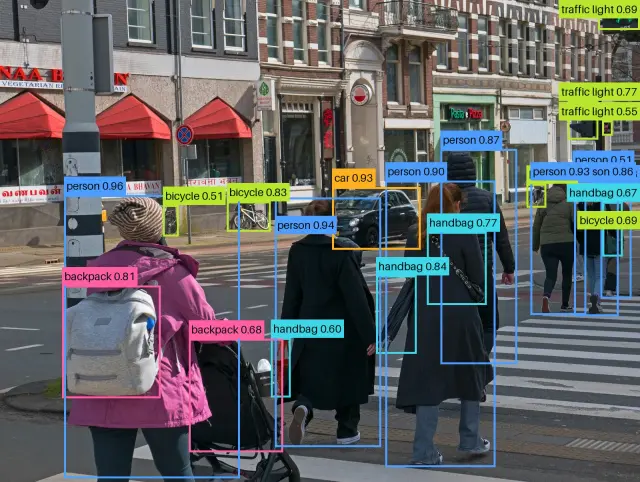 crossing-amsterdamFails: labels the stroller as a backpack
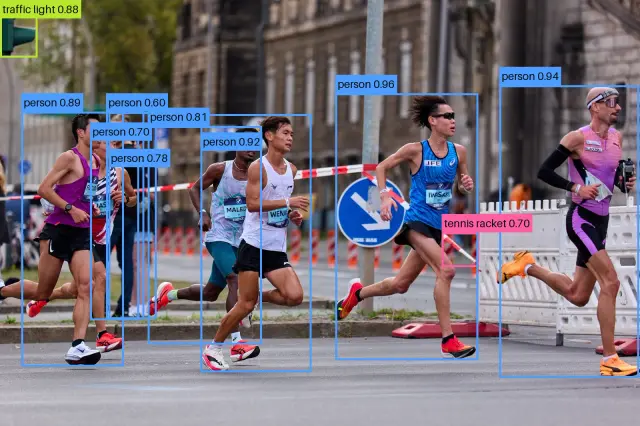 marathon-packFails: labels the barrier tape as a tennis racket
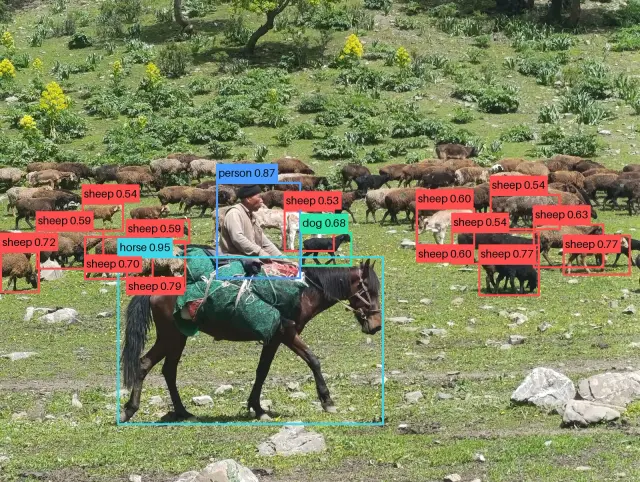 shepherd-sheepFails: labels the black lamb as a dog
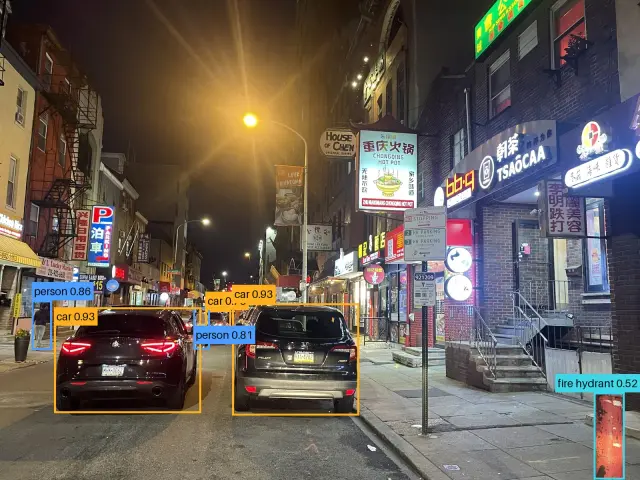 street-night-chinatownFails: labels a red street post as a fire hydrant
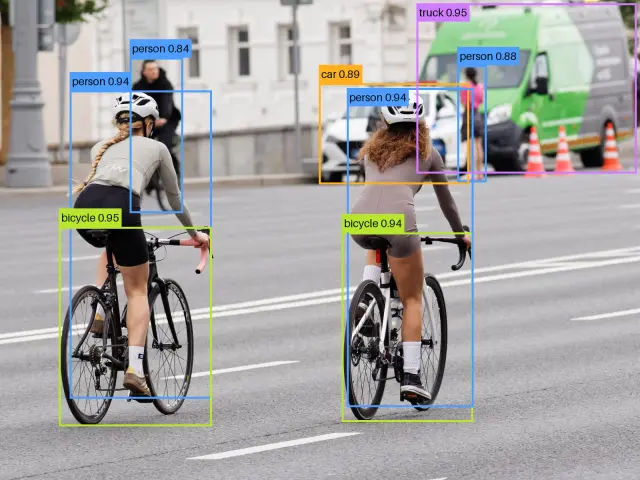 bike-parade-riders
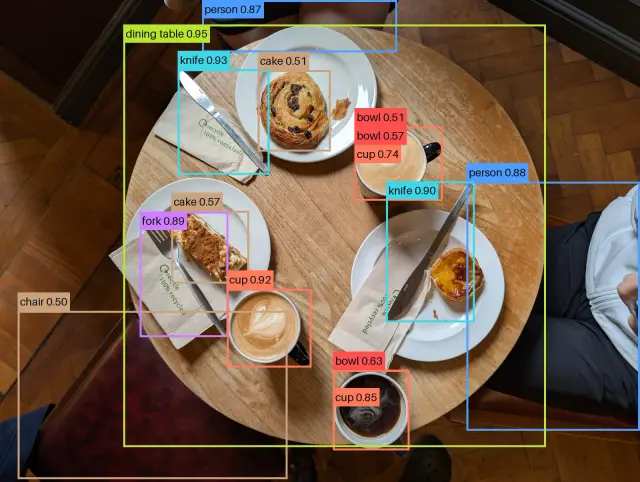 breakfast-top-down
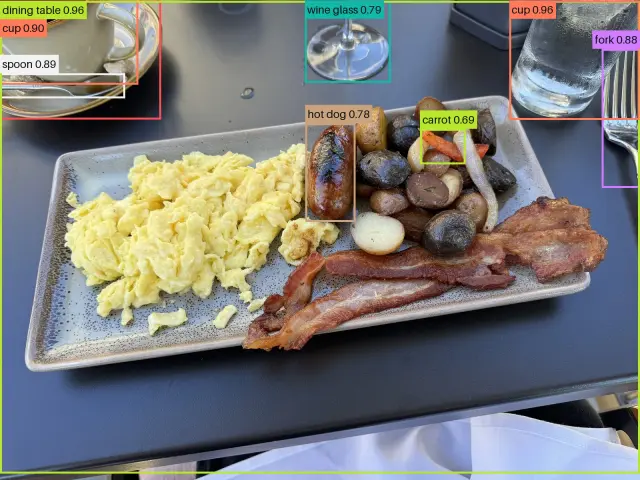 cafe-table-glasses
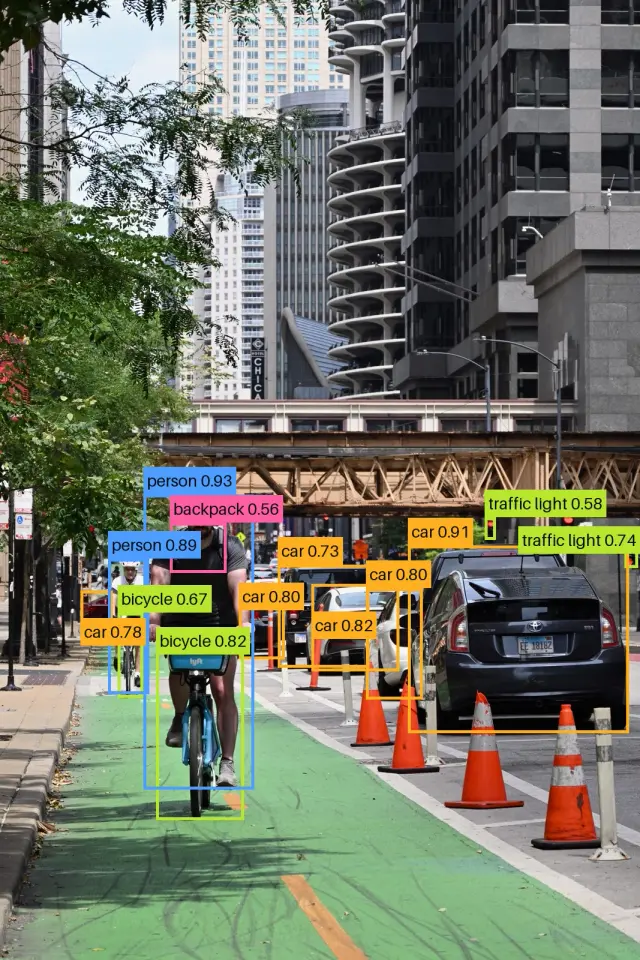 cyclist-bike-lane
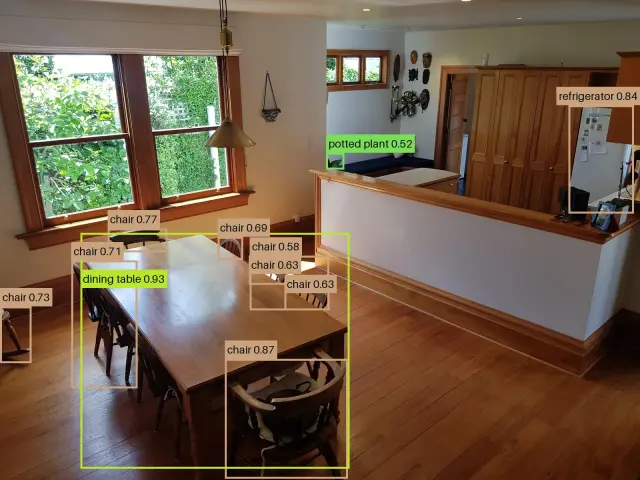 dining-room-kitchen
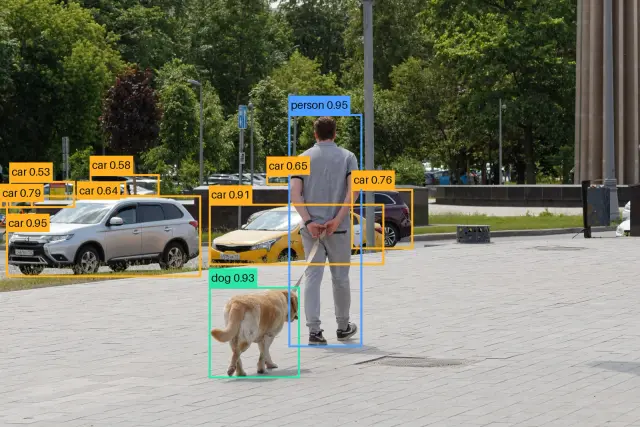 dog-walk-square
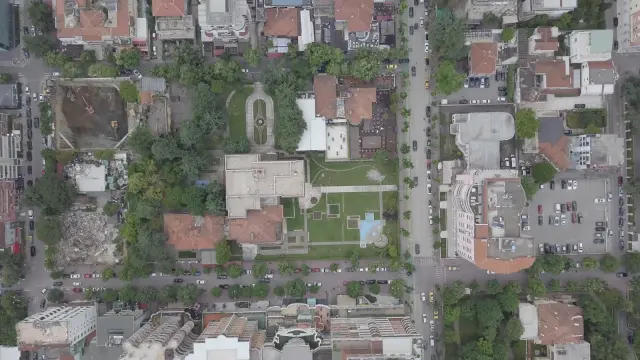 drone-city-block
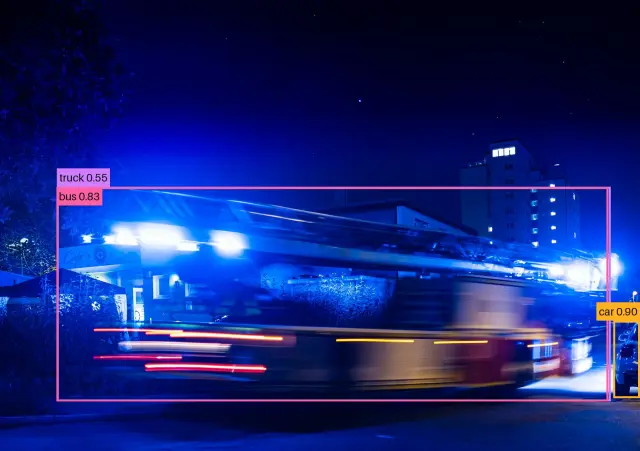 fire-engine-blur
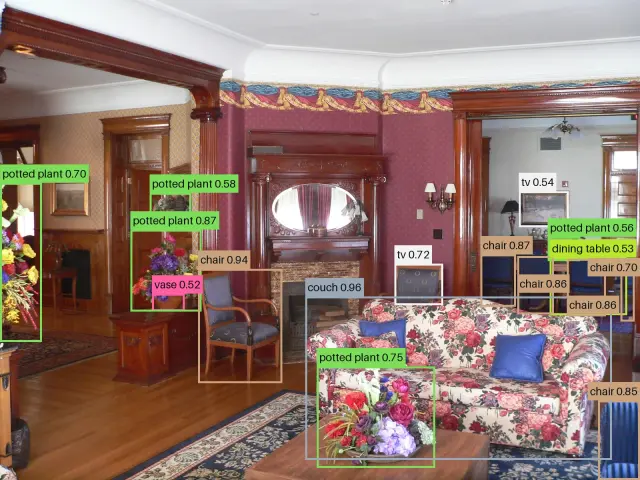 living-room-couch
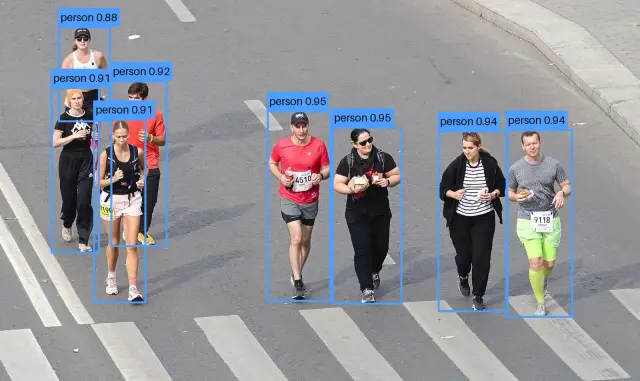 marathon-crossing
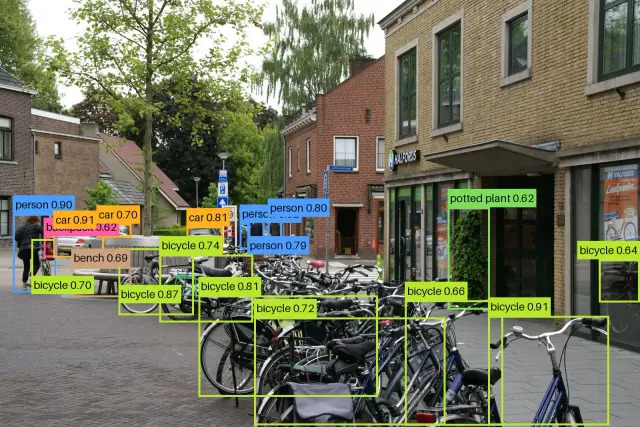 parked-bicycles
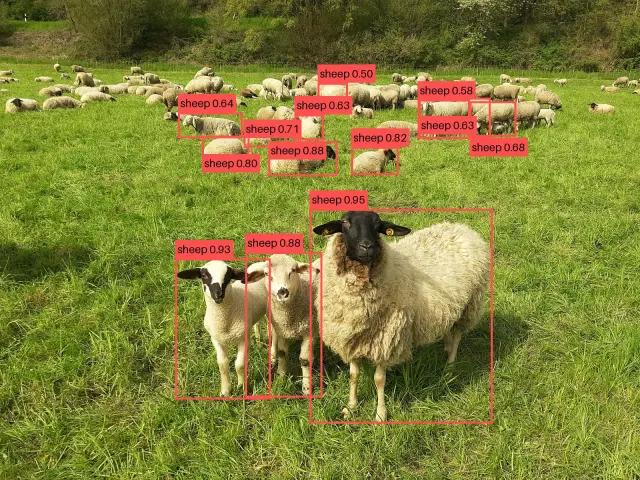 sheep-meadow-lambs
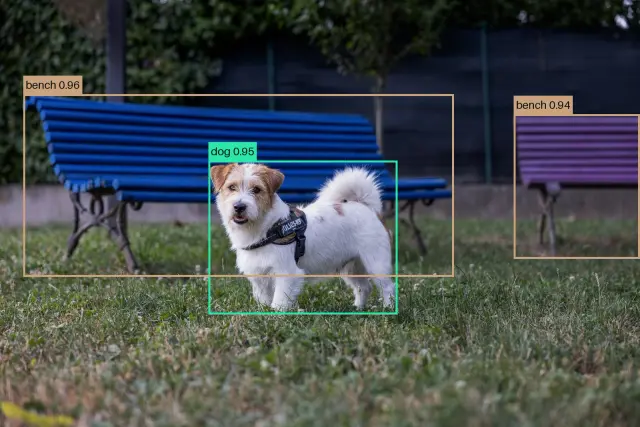 terrier-dog-park
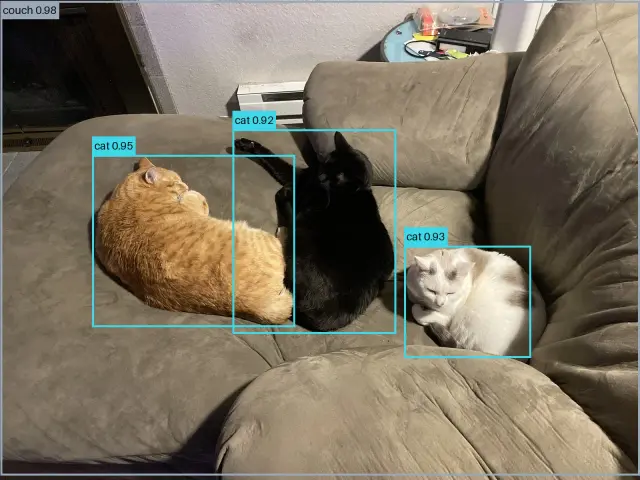 three-cats-couch
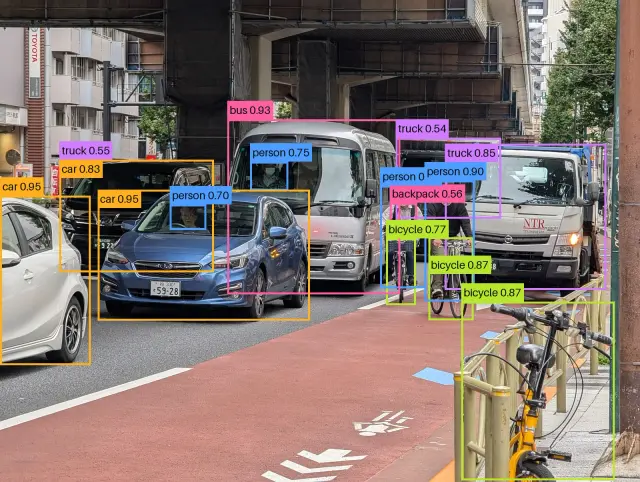 tokyo-street-cyclists
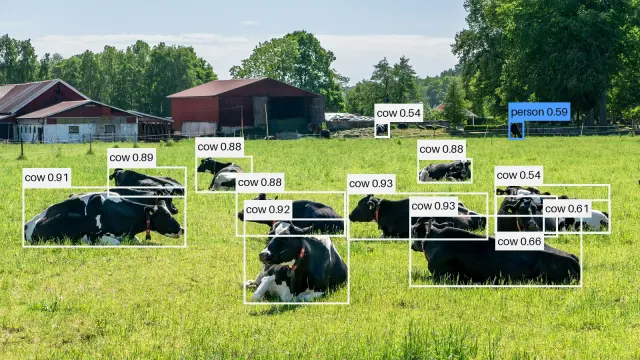 cows-pastureFails: labels a distant cow as a person
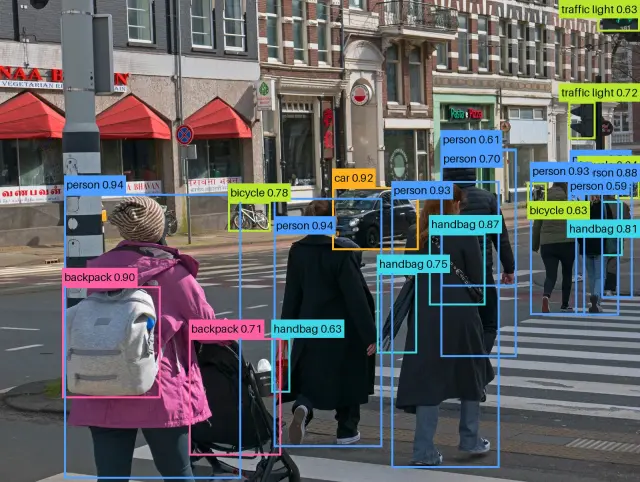 crossing-amsterdamFails: labels the stroller as a backpack
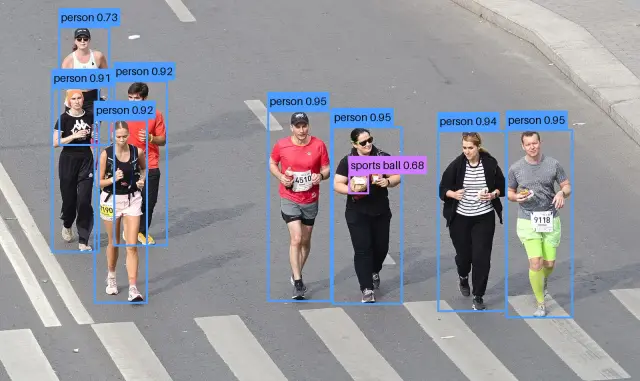 marathon-crossingFails: labels a paper bag as a sports ball
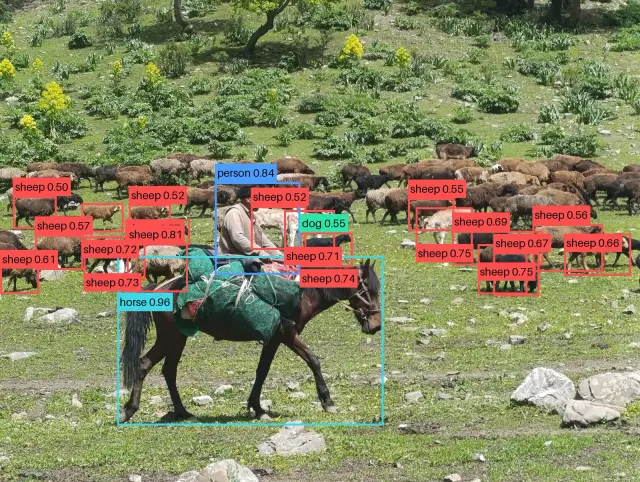 shepherd-sheepFails: labels the black lamb as a dog
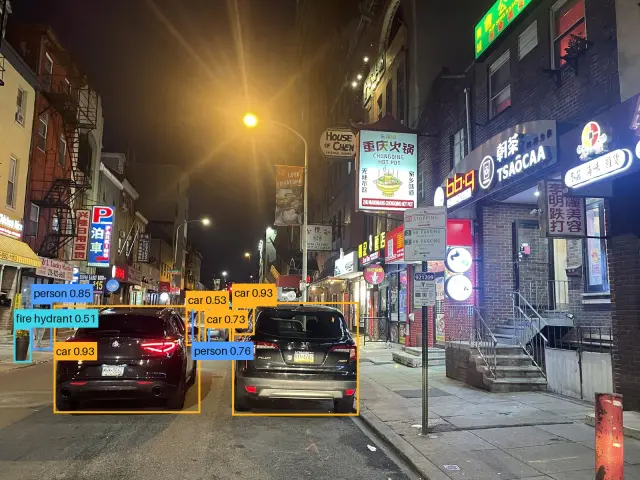 street-night-chinatownFails: labels a sidewalk planter as a fire hydrant
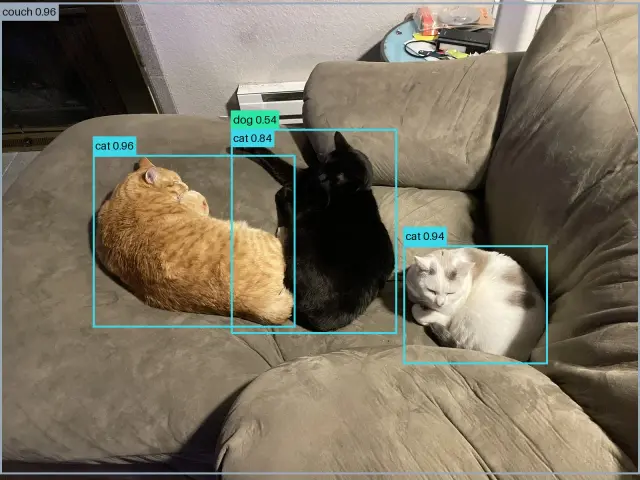 three-cats-couchFails: labels the black cat as a dog
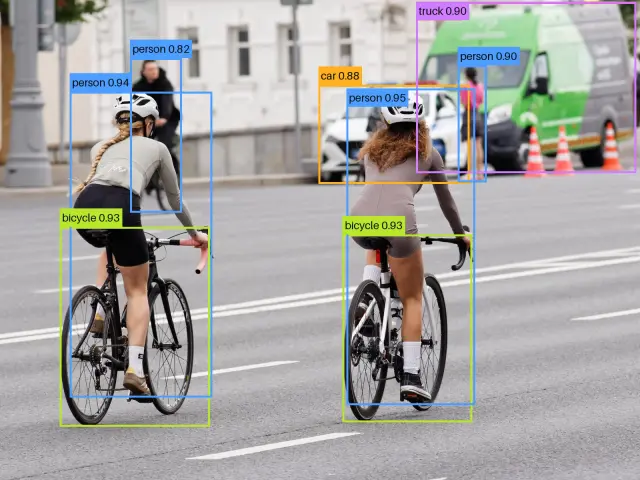 bike-parade-riders
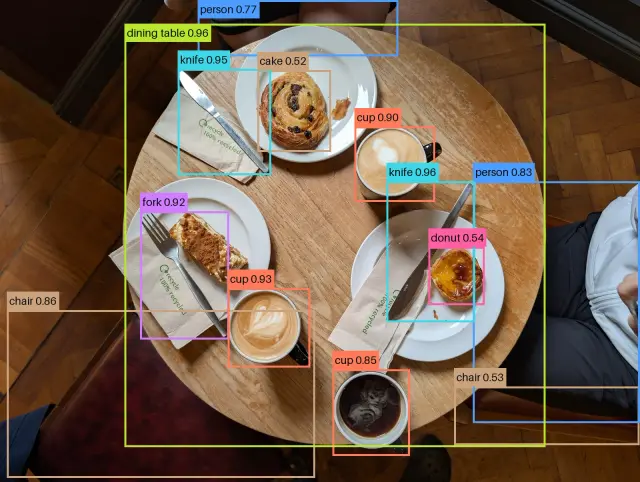 breakfast-top-down
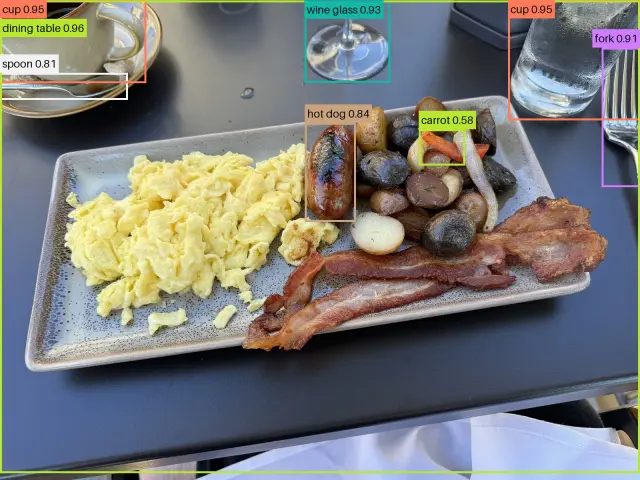 cafe-table-glasses
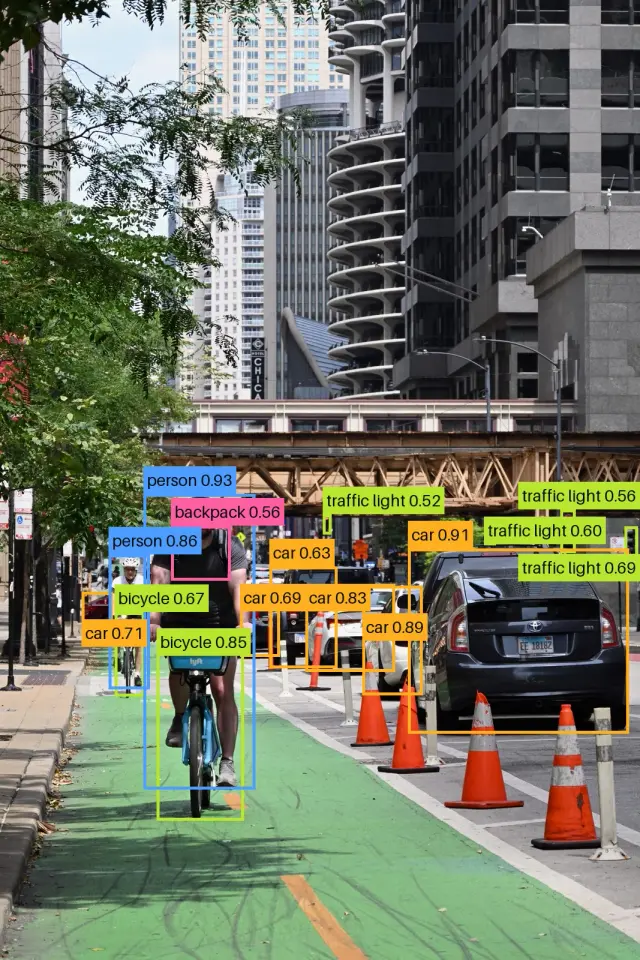 cyclist-bike-lane
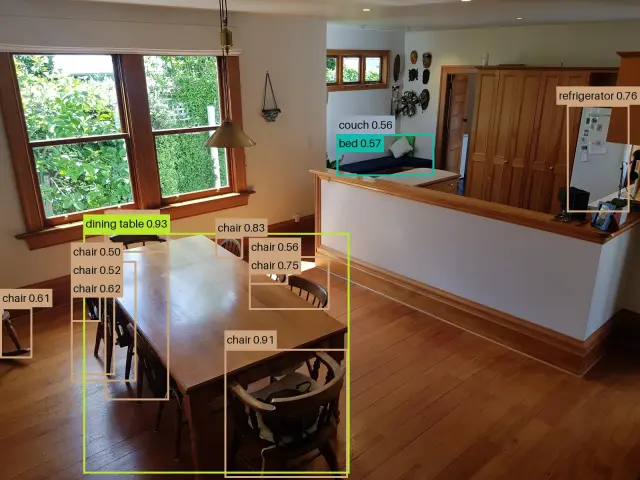 dining-room-kitchen
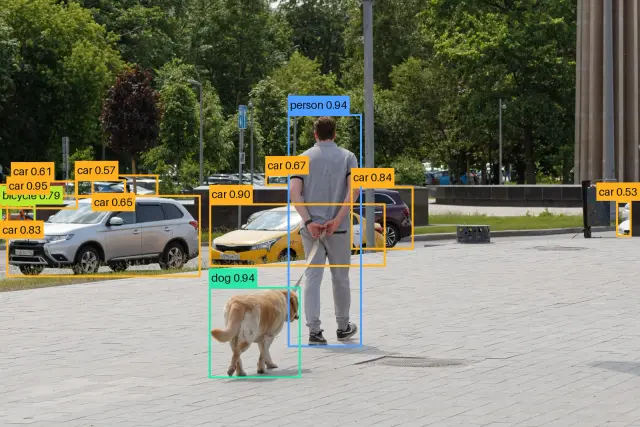 dog-walk-square
- drone-city-block
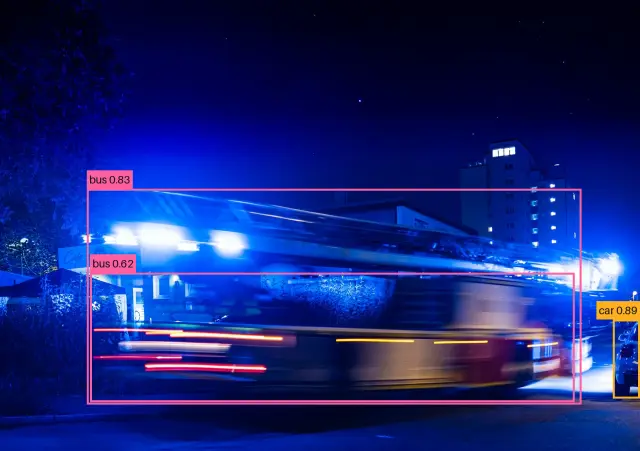 fire-engine-blur
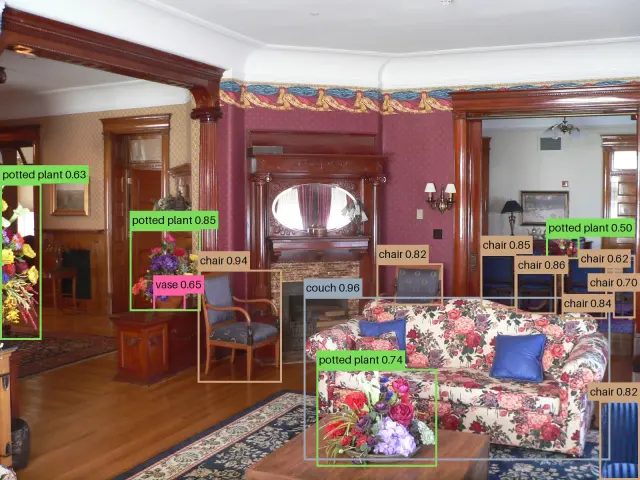 living-room-couch
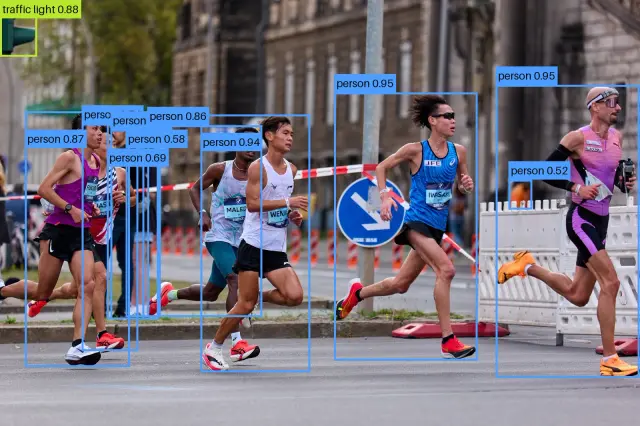 marathon-pack
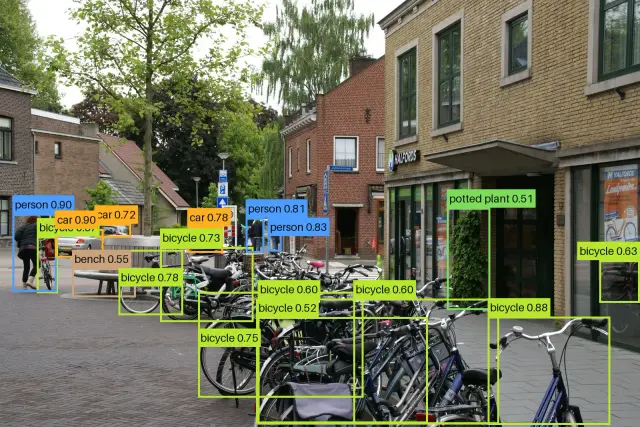 parked-bicycles
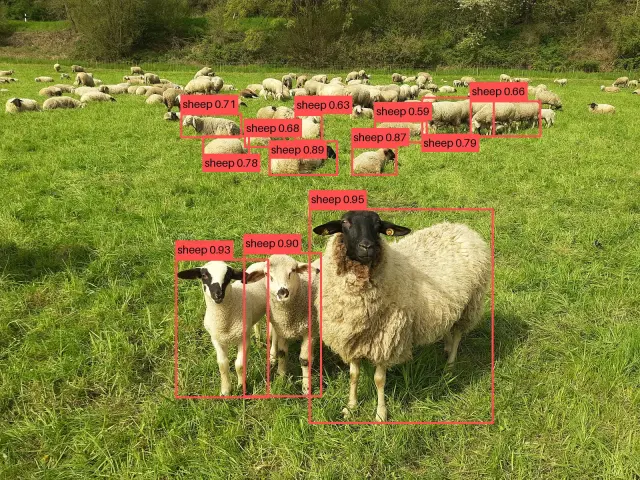 sheep-meadow-lambs
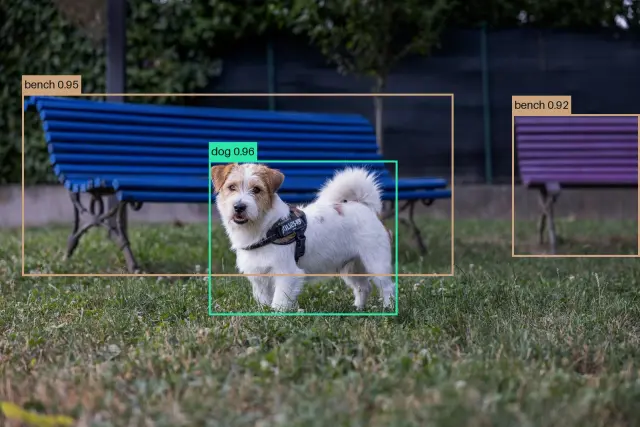 terrier-dog-park
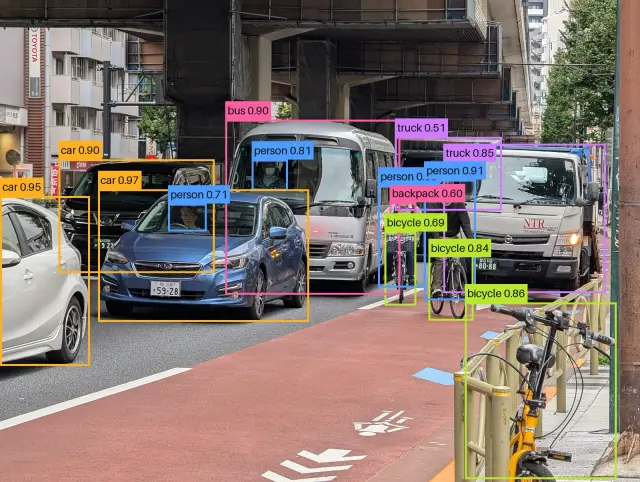 tokyo-street-cyclists
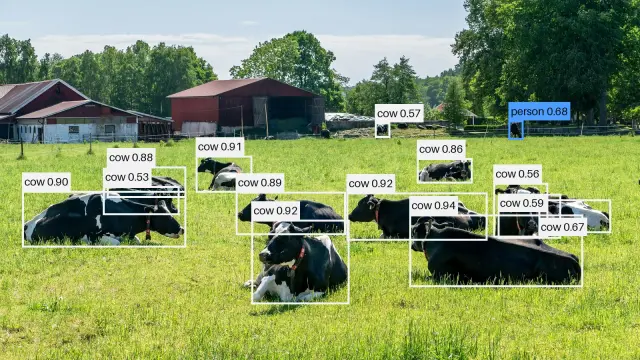 cows-pastureFails: labels a distant cow as a person
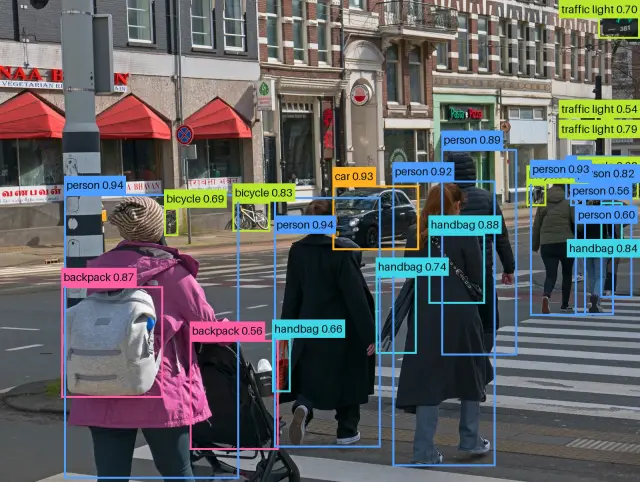 crossing-amsterdamFails: labels the stroller as a backpack
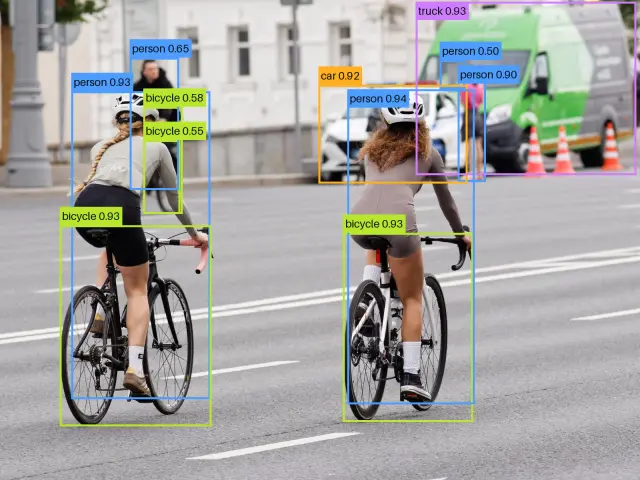 bike-parade-riders
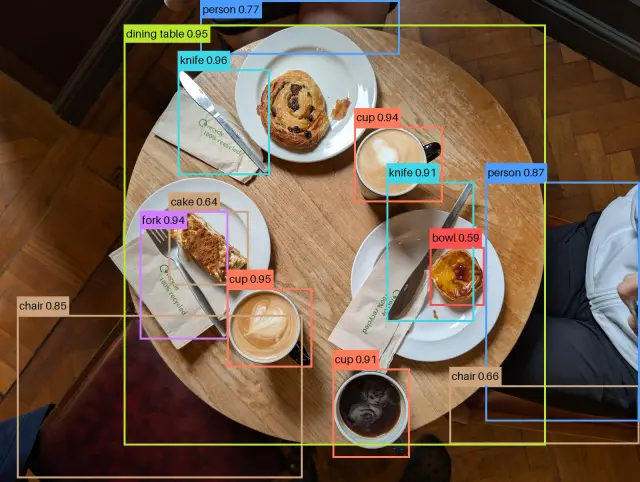 breakfast-top-down
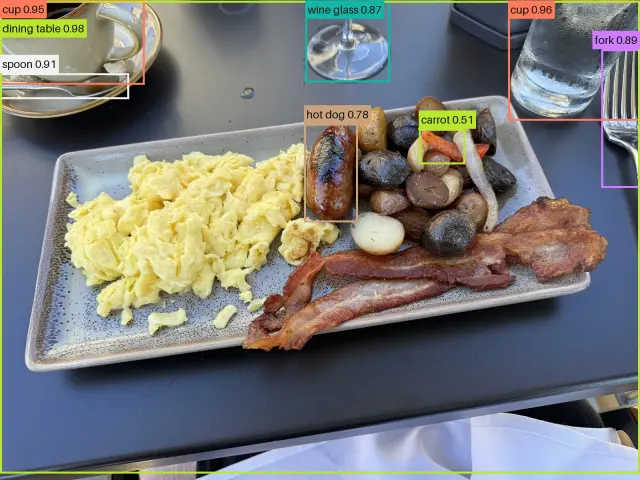 cafe-table-glasses
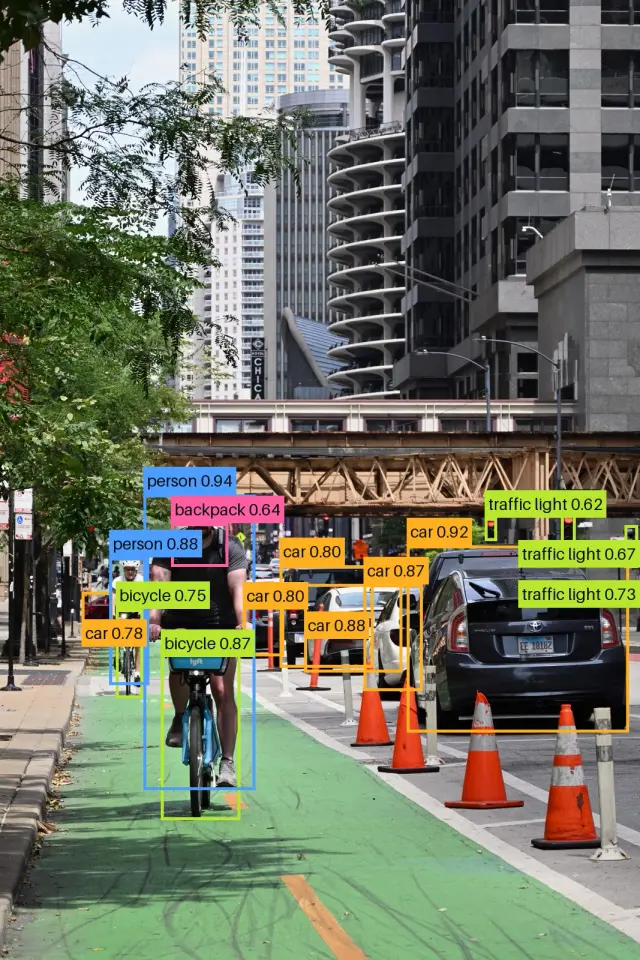 cyclist-bike-lane
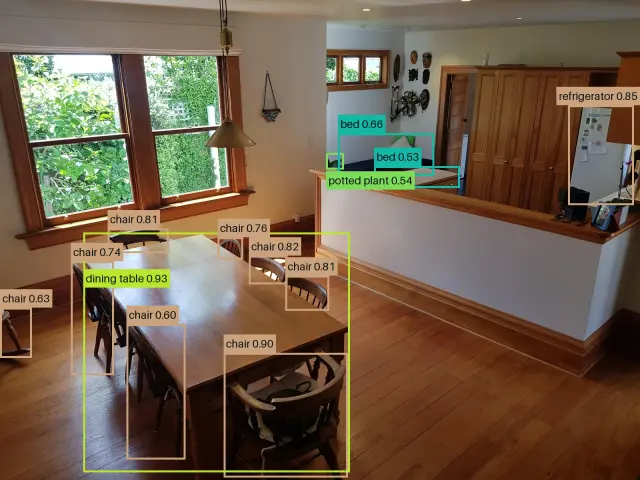 dining-room-kitchen
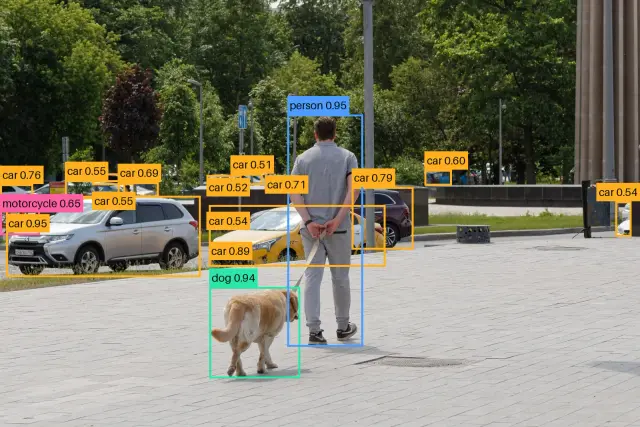 dog-walk-square
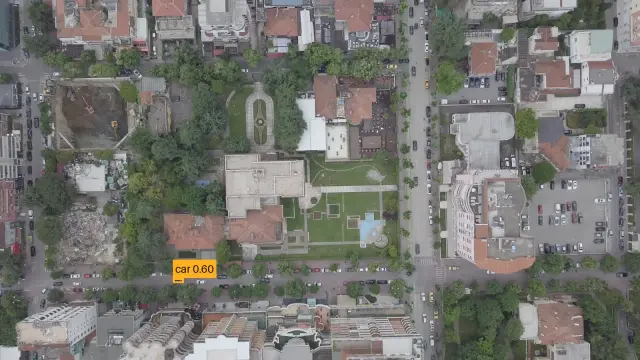 drone-city-block
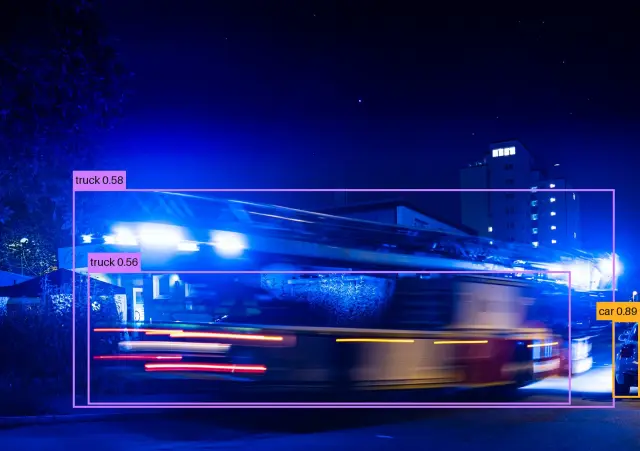 fire-engine-blur
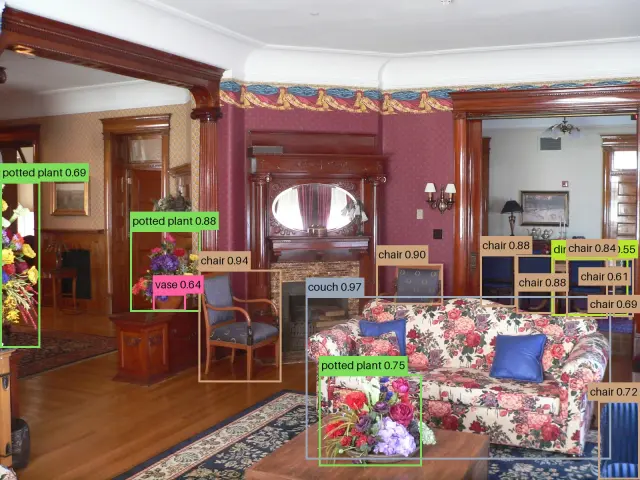 living-room-couch
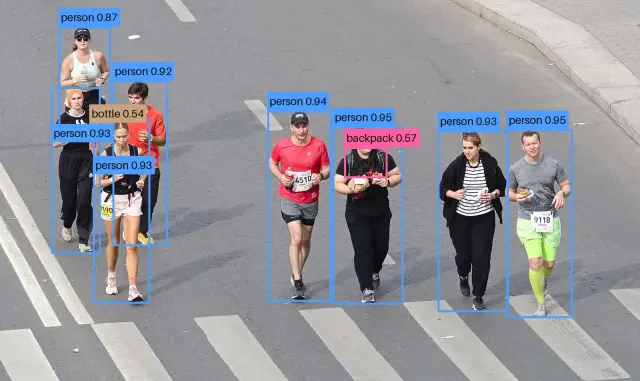 marathon-crossing
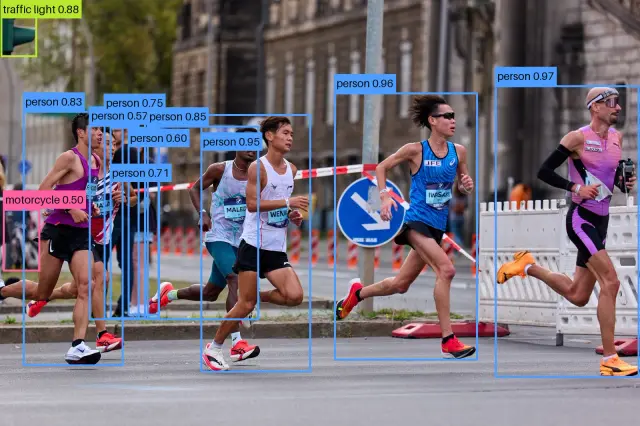 marathon-pack
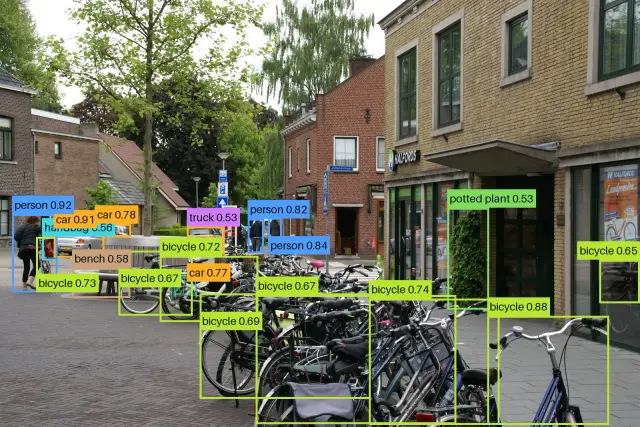 parked-bicycles
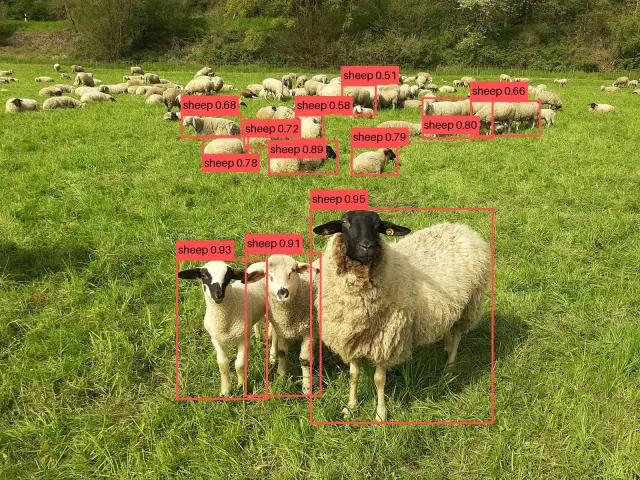 sheep-meadow-lambs
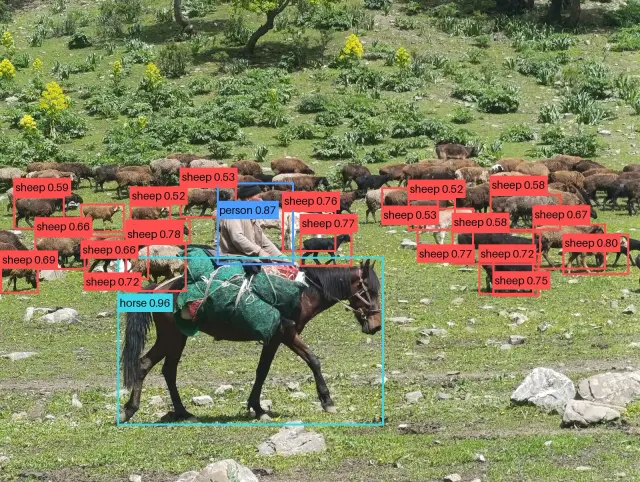 shepherd-sheep
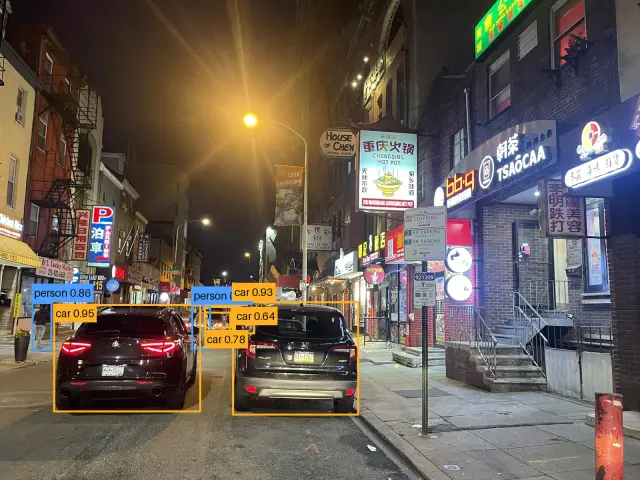 street-night-chinatown
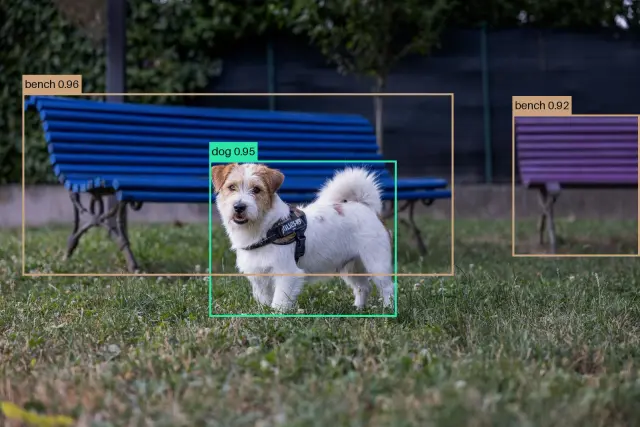 terrier-dog-park
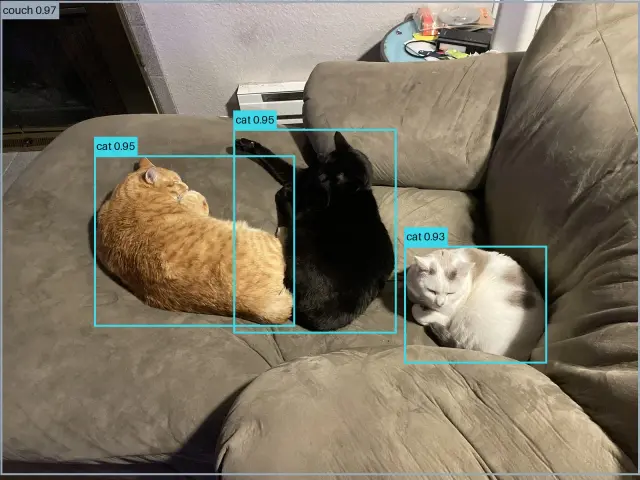 three-cats-couch
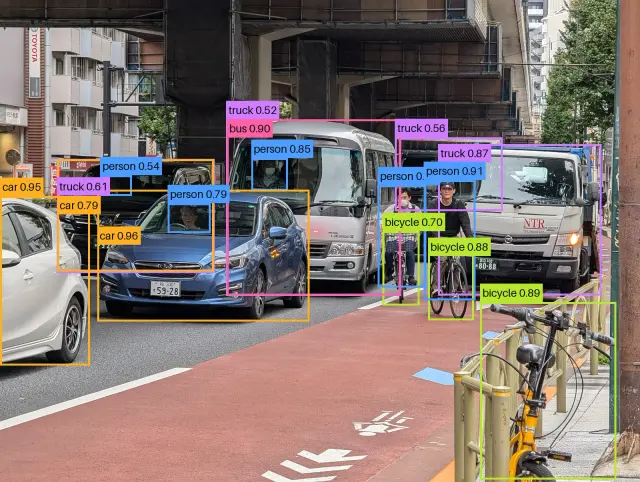 tokyo-street-cyclists
Sizes
| Size | Latency | VRAM | Accuracy | Weights | Runs | License |
|---|---|---|---|---|---|---|
| s | 30.4 ms640x640 | 632 MiB | 51.0 box AP, measured50.7 COCO mAP50-95 paper | 40 MB | As is | Conditional |
| m | 31.6 ms640x640 | 704 MiB | 53.5 box AP, measured53.1 COCO mAP50-95 paper | 81 MB | As is | Conditional |
| l | 32.2 ms640x640 | 768 MiB | 56.4 box AP, measured56 COCO mAP50-95 paper | 129 MB | As is | Conditional |
Estimated on other GPUs
Estimate, not measured. Worked out from our RTX 4090 run and NVIDIA's spec sheets. Each kind of GPU work is scaled by that GPU's peak for it: tensor cores at the precision the kernels used, CUDA cores, or memory bandwidth. The CPU's part of each call is kept at what it took on our Intel Core i7-10700K. How we estimate
Where a call's time goes on our RTX 4090: CPU and kernel launches 86%, memory-bound 8%, tensor cores, FP16 (FP32 accumulate) 4%, host–device copies 2%.
GeForce (13)
| GPU | Fits | Latency |
|---|---|---|
| GeForce RTX 5090Blackwell, 32 GB GDDR7 | Yes | ≈ 29–30 ms |
| GeForce RTX 5080Blackwell, 16 GB GDDR7 | Yes | ≈ 31 ms |
| GeForce RTX 5070 TiBlackwell, 16 GB GDDR7 | Yes | ≈ 31–32 ms |
| GeForce RTX 5070Blackwell, 12 GB GDDR7 | Yes | ≈ 31–34 ms |
| GeForce RTX 5060 Ti 16GBBlackwell, 16 GB GDDR7 | Yes | ≈ 32–37 ms |
| GeForce RTX 5060Blackwell, 8 GB GDDR7 | Yes | ≈ 33–38 ms |
| GeForce RTX 4080Ada Lovelace, 16 GB GDDR6X | Yes | ≈ 31–32 ms |
| GeForce RTX 4070 TiAda Lovelace, 12 GB GDDR6X | Yes | ≈ 31–34 ms |
| GeForce RTX 4070Ada Lovelace, 12 GB GDDR6X | Yes | ≈ 32–35 ms |
| GeForce RTX 3090Ampere, 24 GB GDDR6X | Yes | ≈ 31–32 ms |
| GeForce RTX 3080Ampere, 10 GB GDDR6X | Yes | ≈ 31–33 ms |
| GeForce RTX 3070 TiAmpere, 8 GB GDDR6X | Yes | ≈ 32–36 ms |
| GeForce RTX 3070Ampere, 8 GB GDDR6 | Yes | ≈ 32–37 ms |
Workstation (4)
| GPU | Fits | Latency |
|---|---|---|
| RTX PRO 6000 Blackwell Workstation EditionBlackwell, 96 GB GDDR7 | Yes | ≈ 29–30 ms |
| RTX PRO 6000 Blackwell Max-Q Workstation EditionBlackwell, 96 GB GDDR7 | Yes | ≈ 29–30 ms |
| RTX 6000 Ada GenerationAda Lovelace, 48 GB GDDR6 | Yes | ≈ 30 ms |
| RTX A6000Ampere, 48 GB GDDR6 | Yes | ≈ 31 ms |
Data center (6)
| GPU | Fits | Latency |
|---|---|---|
| B200 (HGX, one GPU)Blackwell, 180 GB HBM3E | Yes | ≈ 27–30 ms |
| H200 SXMHopper, 141 GB HBM3e | Yes | ≈ 27–30 ms |
| H100 SXMHopper, 80 GB HBM3 | Yes | ≈ 28–30 ms |
| A100 SXM 80GBAmpere, 80 GB HBM2e | Yes | ≈ 29–30 ms |
| L40SAda Lovelace, 48 GB GDDR6 | Yes | ≈ 30 ms |
| L4Ada Lovelace, 24 GB GDDR6 | Yes | ≈ 31–37 ms |
Where a call's time goes on our RTX 4090: CPU and kernel launches 84%, memory-bound 9%, tensor cores, FP16 (FP32 accumulate) 5%, host–device copies 2%.
GeForce (13)
| GPU | Fits | Latency |
|---|---|---|
| GeForce RTX 5090Blackwell, 32 GB GDDR7 | Yes | ≈ 30–31 ms |
| GeForce RTX 5080Blackwell, 16 GB GDDR7 | Yes | ≈ 32–33 ms |
| GeForce RTX 5070 TiBlackwell, 16 GB GDDR7 | Yes | ≈ 32–33 ms |
| GeForce RTX 5070Blackwell, 12 GB GDDR7 | Yes | ≈ 33–36 ms |
| GeForce RTX 5060 Ti 16GBBlackwell, 16 GB GDDR7 | Yes | ≈ 34–39 ms |
| GeForce RTX 5060Blackwell, 8 GB GDDR7 | Yes | ≈ 35–41 ms |
| GeForce RTX 4080Ada Lovelace, 16 GB GDDR6X | Yes | ≈ 32–34 ms |
| GeForce RTX 4070 TiAda Lovelace, 12 GB GDDR6X | Yes | ≈ 33–36 ms |
| GeForce RTX 4070Ada Lovelace, 12 GB GDDR6X | Yes | ≈ 33–38 ms |
| GeForce RTX 3090Ampere, 24 GB GDDR6X | Yes | ≈ 33–34 ms |
| GeForce RTX 3080Ampere, 10 GB GDDR6X | Yes | ≈ 33–36 ms |
| GeForce RTX 3070 TiAmpere, 8 GB GDDR6X | Yes | ≈ 34–38 ms |
| GeForce RTX 3070Ampere, 8 GB GDDR6 | Yes | ≈ 35–40 ms |
Workstation (4)
| GPU | Fits | Latency |
|---|---|---|
| RTX PRO 6000 Blackwell Workstation EditionBlackwell, 96 GB GDDR7 | Yes | ≈ 29–31 ms |
| RTX PRO 6000 Blackwell Max-Q Workstation EditionBlackwell, 96 GB GDDR7 | Yes | ≈ 29–31 ms |
| RTX 6000 Ada GenerationAda Lovelace, 48 GB GDDR6 | Yes | ≈ 31 ms |
| RTX A6000Ampere, 48 GB GDDR6 | Yes | ≈ 32–33 ms |
Data center (6)
| GPU | Fits | Latency |
|---|---|---|
| B200 (HGX, one GPU)Blackwell, 180 GB HBM3E | Yes | ≈ 28–31 ms |
| H200 SXMHopper, 141 GB HBM3e | Yes | ≈ 28–31 ms |
| H100 SXMHopper, 80 GB HBM3 | Yes | ≈ 28–31 ms |
| A100 SXM 80GBAmpere, 80 GB HBM2e | Yes | ≈ 30–31 ms |
| L40SAda Lovelace, 48 GB GDDR6 | Yes | ≈ 31 ms |
| L4Ada Lovelace, 24 GB GDDR6 | Yes | ≈ 33–39 ms |
Where a call's time goes on our RTX 4090: CPU and kernel launches 82%, memory-bound 10%, tensor cores, FP16 (FP32 accumulate) 7%, host–device copies 2%.
GeForce (13)
| GPU | Fits | Latency |
|---|---|---|
| GeForce RTX 5090Blackwell, 32 GB GDDR7 | Yes | ≈ 30–32 ms |
| GeForce RTX 5080Blackwell, 16 GB GDDR7 | Yes | ≈ 33 ms |
| GeForce RTX 5070 TiBlackwell, 16 GB GDDR7 | Yes | ≈ 33–35 ms |
| GeForce RTX 5070Blackwell, 12 GB GDDR7 | Yes | ≈ 34–38 ms |
| GeForce RTX 5060 Ti 16GBBlackwell, 16 GB GDDR7 | Yes | ≈ 35–42 ms |
| GeForce RTX 5060Blackwell, 8 GB GDDR7 | Yes | ≈ 36–44 ms |
| GeForce RTX 4080Ada Lovelace, 16 GB GDDR6X | Yes | ≈ 33–35 ms |
| GeForce RTX 4070 TiAda Lovelace, 12 GB GDDR6X | Yes | ≈ 34–38 ms |
| GeForce RTX 4070Ada Lovelace, 12 GB GDDR6X | Yes | ≈ 35–40 ms |
| GeForce RTX 3090Ampere, 24 GB GDDR6X | Yes | ≈ 34–35 ms |
| GeForce RTX 3080Ampere, 10 GB GDDR6X | Yes | ≈ 34–37 ms |
| GeForce RTX 3070 TiAmpere, 8 GB GDDR6X | Yes | ≈ 36–41 ms |
| GeForce RTX 3070Ampere, 8 GB GDDR6 | Yes | ≈ 36–43 ms |
Workstation (4)
| GPU | Fits | Latency |
|---|---|---|
| RTX PRO 6000 Blackwell Workstation EditionBlackwell, 96 GB GDDR7 | Yes | ≈ 29–31 ms |
| RTX PRO 6000 Blackwell Max-Q Workstation EditionBlackwell, 96 GB GDDR7 | Yes | ≈ 29–31 ms |
| RTX 6000 Ada GenerationAda Lovelace, 48 GB GDDR6 | Yes | ≈ 31–32 ms |
| RTX A6000Ampere, 48 GB GDDR6 | Yes | ≈ 32–33 ms |
Data center (6)
| GPU | Fits | Latency |
|---|---|---|
| B200 (HGX, one GPU)Blackwell, 180 GB HBM3E | Yes | ≈ 28–31 ms |
| H200 SXMHopper, 141 GB HBM3e | Yes | ≈ 28–31 ms |
| H100 SXMHopper, 80 GB HBM3 | Yes | ≈ 28–31 ms |
| A100 SXM 80GBAmpere, 80 GB HBM2e | Yes | ≈ 30–32 ms |
| L40SAda Lovelace, 48 GB GDDR6 | Yes | ≈ 32 ms |
| L4Ada Lovelace, 24 GB GDDR6 | Yes | ≈ 34–41 ms |
Alternatives
Something wrong on this page, such as a license or a number? Email us.